{"summary":"Assistants that answer and qualify inquiries day and night, search that finds the right answer in your own documents, and automations that take repetitive work off your team. Built to run in production, not as a demo.","keyCapabilities":["Lead-Qualifying Chat Assistants (like Fyra)","Search & Q&A over Your Documents (RAG)","Workflow Automation Across Forms, Email & Sheets","Document & Data Extraction","Computer Vision & Gesture Tracking (OpenCV, MediaPipe)","Edge AI on Low-Cost Devices (TensorFlow Lite)"],"technologiesUsed":["Gemini API","OpenAI API","Claude API","Ollama (local open models)","pgvector (Postgres / Supabase)","LangChain (Python/TS)","Edge Impulse (Edge ML)","TensorFlow Lite Converter","OpenCV (C++ / Python)","MediaPipe (Hand & Pose Tracking)","NumPy / Scikit-Learn","Matplotlib","Next.js App Router API Routes","Supabase Edge Functions","PlatformIO (ESP32 C++)","FastAPI (Python)"],"typicalDeliverables":["Vector Search Schemas","Custom Prompt Templates & Handlers","Quantized Edge AI Model Files","Next.js Streaming Handlers","Computer Vision Scripts"],"supportedIndustries":["SaaS & Web Services","Health & Clinical Research","Robotics & Physical Labs"],"relatedProjects":["Fyra — AI Portfolio Assistant","SmartPot — AI Plant Companion","Smart Robotic Arm"]}
AI automation for UK businesses
UK agencies and small firms usually need less AI than they think: an assistant for first-line inquiries, search across your own paperwork, and fewer manual hand-offs. I build those from Assam and we review them in your morning.
Process Audit → Working Pilot → Production Rollout
Platforms Used
Google Gemini APIClaude / OpenAI APIsSupabase VectorNext.js
Working with me from the UK
What clients there usually need
A first-line inquiry assistant for an agency site that answers service questions and passes qualified enquiries to the right account manager.
Search across your proposals, contracts and past project folders, so a new project lead finds precedent without asking colleagues.
Automation that takes a booking form, creates the job in your tracker, emails the client and reminds staff the day before.
A drafting assistant that turns meeting notes into client follow-up emails in your house tone, always left for a person to approve.
India is 4½ hours ahead of the UK in summer and 5½ in winter, because UK clocks change on their own schedule and India's do not. Your 9 am to 1 pm is my 1:30 to 5:30 pm in summer and 2:30 to 6:30 pm in winter, which is enough for calls, reviews and quick questions. The gap moves twice a year, so we agree call times and update rhythm at the start.
I quote in USD and you pay by Wise or international bank transfer. Pay from your pound account and your bank or Wise converts the amount, so you can see the exact rate before you send it. Invoices are in English. A contract or NDA can be signed electronically, DocuSign-style, and I am happy to sign your NDA first. I do not give tax or legal advice, so please check the details with your accountant.
I can write copy, interface text and documentation in UK English spelling if you want it, so colour, organisation and licence match your brand. Agencies are welcome to white-label the work: you stay the face to your client, and I work quietly behind you under your NDA, with code in your GitHub from day one. Tell me how you prefer to run it and I will fit in.
Optimization Summary
Generic AI chatbots hallucinate and suffer from high API costs. I build structured RAG pipelines and local classifiers to keep logic strict.
Common Obstacle
“AI chatbot hallucinates details or invents services I don't offer.”
Engineering Resolution
I implement strict semantic search routing using vector embeddings (via Supabase Vector). The system forces the LLM to reply only using retrieved context, falling back to a structured brief capture form if the query is out-of-bounds.
Common Obstacle
“API token costs are skyrocketing and response times are too slow.”
Engineering Resolution
I write lightweight token buckets and rate limiters. For simple patterns, I build local classifiers, compile local models, or trim prompt size and cache repeat answers so API costs stay predictable.
Common Obstacle
“Staff spend hours copying data between forms, email and spreadsheets.”
Engineering Resolution
I connect your tools through their APIs so data moves on its own, and add an AI step only where judgement is needed: sorting inquiries, extracting fields from documents, drafting replies for a human to approve.
Common Obstacle
“Running AI models on device requires too much RAM and power.”
Engineering Resolution
I quantize neural networks (using TensorFlow Lite) into 8-bit integers, reducing flash footprints. We run models locally on edge processors (ESP32-S3 or Jetson Nano) so responses stay quick without a cloud round trip.
Is This Service Right for You?
I build AI that does a specific job for your business and plugs into the tools you already use. I don't sell generic wrapper bots.
Businesses with Repetitive Inquiries
Teams answering the same questions on the website, WhatsApp or email every day. Fyra, the assistant on this site, answers visitors, recommends work and captures qualified leads.
Offices with Too Many Documents
Colleges, clinics and firms whose answers are buried in PDFs and policies, and who need search that cites the source instead of guessing.
Teams Doing Repetitive Admin
Copying data between forms, inboxes and spreadsheets, sending the same follow-ups, building the same weekly report. These are the first things to automate.
Hardware & Vision Projects
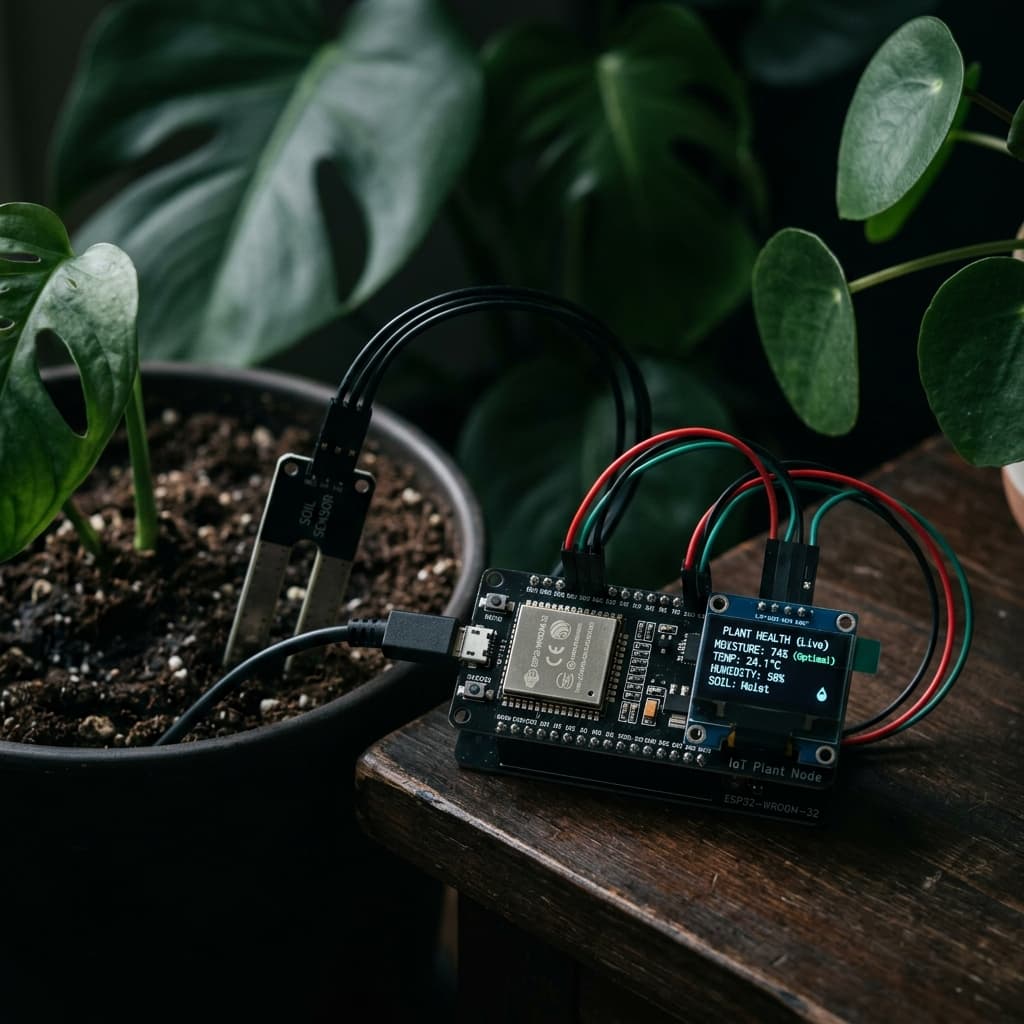
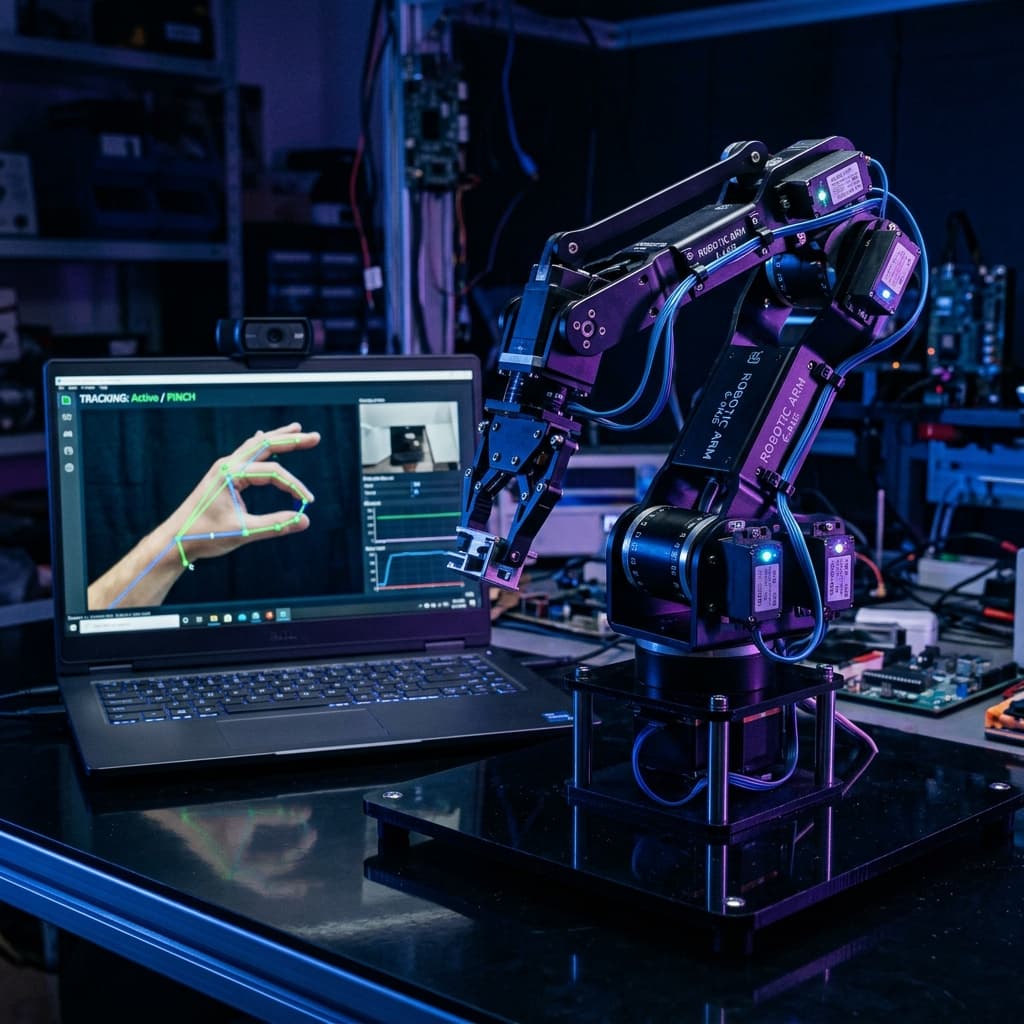
Products that need to see or hear: gesture tracking driving motors (like my robotic arm) or on-device models on an ESP32 (like SmartPot).
Typical AI Deliverables
Fully deployed, validated, and open-source models ready to integrate with your existing codebase.
Database
Vector Search Schemas
Fully configured Supabase Postgres tables with pgvector extensions, semantic similarity functions, and index scaling configurations.
Software
Custom Prompt Templates & Handlers
Clean, parameterized system prompts and prompt engineering scripts structured to prevent prompt injection and keep models aligned.
API route endpoint codes implementing SSE (Server-Sent Events) or WebSockets to stream conversational responses character-by-character.
Software
Computer Vision Scripts
Python / C++ scripts utilizing OpenCV and MediaPipe pipelines to track hands, detect faces, or classify target products.
Specialized Building Areas
I bridge raw web components and edge hardware using practical AI modules.
Intelligent Conversational Agents
Bespoke assistant nodes. I design chat interfaces (like Fyra AI) that leverage LLM streaming, identify user intent, extract fields (timeline, budget), and switch viewports automatically.
Local Computer Vision pipelines
Camera-driven logic. I compile lightweight tracking codes processing webcam coordinates at 30FPS to translate joint movements into physical commands with minimal jitter.
On-Chip Audio & Neural Classifiers
Edge AI. I train wake-word models and local audio classifiers using Edge Impulse, exporting lightweight libraries that compile directly inside ESP32-S3 boards.
Technical Stack & Platform Coverage
I build AI systems using modern vector databases and optimized inference runtimes.
Large Language Models & APIs
Gemini APIOpenAI APIClaude APIOllama (local open models)
Vector Databases & Frameworks
pgvector (Postgres / Supabase)LangChain (Python/TS)Edge Impulse (Edge ML)TensorFlow Lite Converter
In corporate environments, generic AI chatbots are liability hazards due to hallucinations. Solving this requires scoping queries strictly using a Postgres vector database extension (pgvector) to verify factual boundaries before invoking the Large Language Model.
Cosine Similarity Scoping
When querying vector databases, setting a static similarity threshold (e.g. similarity > 0.7) is often insufficient. Different documents generate varying density ranges. Implementing a dynamic ranking algorithm that combines full-text search (BM25) with vector similarity (HNSW index) provides far better results and filters out irrelevant prompts before they reach the API.
Below is the SQL implementation I execute to build semantic search indexing and custom matching inside Supabase:
-- Create database schema to store technical document embeddings
CREATE EXTENSION IF NOT EXISTS pgvector;

CREATE TABLE IF NOT EXISTS document_chunks (
  id           UUID PRIMARY KEY DEFAULT gen_random_uuid(),
  content      TEXT NOT NULL,
  metadata     JSONB,
  embedding    vector(1536) -- Match standard OpenAI / Gemini embedding dimensions
);

-- Build Hierarchical Navigable Small World (HNSW) index for sub-millisecond retrieval
CREATE INDEX ON document_chunks USING hnsw (embedding vector_cosine_ops);

-- Create database function to perform cosine similarity search
CREATE OR REPLACE FUNCTION match_documents (
  query_embedding vector(1536),
  match_threshold float,
  match_count int
)
RETURNS TABLE (
  id uuid,
  content text,
  metadata jsonb,
  similarity float
)
LANGUAGE plpgsql AS $$
BEGIN
  RETURN QUERY
  SELECT
    dc.id,
    dc.content,
    dc.metadata,
    1 - (dc.embedding <=> query_embedding) AS similarity
  FROM document_chunks dc
  WHERE 1 - (dc.embedding <=> query_embedding) > match_threshold
  ORDER BY dc.embedding <=> query_embedding
  LIMIT match_count;
END;
$$;
System Prompt Sandboxing
Always wrap retrieved context fragments inside system boundaries, instructing the model to decline answering if the data is not present in the injected tags. This eliminates typical hallucination routes.
2. Edge AI Model Quantization for Microcontrollers
Running deep learning models locally on edge microcontrollers (like wake-word detection or gesture classification) requires converting 32-bit floats into 8-bit integers using Post-Training Quantization (PTQ).
Unquantized Models on ESP32
A common mistake is attempting to compile standard Keras or PyTorch models directly to microcontrollers. High parameter sizes will trigger immediate memory allocation failures (out of memory) during load. Quantization is mandatory to squeeze weights into the ESP32-S3's 512KB SRAM.
The Post-Training Quantization Pipeline in Python:
Quantization Configuration: Use tf.lite.TFLiteConverter to scale parameters.
Representative Dataset: Feed a sample dataset to map float parameters to integer ranges.
Flashing Header Export: Convert the resulting .tflite model into a C++ hex byte array to compile directly with the firmware source.
import tensorflow as tf

# Load baseline float model
converter = tf.lite.TFLiteConverter.from_saved_model('model_dir')
converter.optimizations = [tf.lite.Optimize.DEFAULT]

# Define representative dataset for integer range mapping
def representative_dataset():
    for data in sample_data_generator():
        yield [data.astype(np.float32)]

converter.representative_dataset = representative_dataset
converter.target_spec.supported_ops = [tf.lite.OpsSet.TFLITE_BUILTINS_INT8]
converter.inference_input_type = tf.int8
converter.inference_output_type = tf.int8

# Convert and save
quantized_model = converter.convert()
with open('wake_word_model.tflite', 'wb') as f:
    f.write(quantized_model)
SmartPot Edge Classifier
During the SmartPot companion development, the unquantized wake-word model was 1.2MB, failing to fit inside flash. After applying 8-bit integer quantization, the model footprint dropped to 142KB, running inference in 42ms on the ESP32-S3 core while retaining 96.4% classification accuracy.
3. Real-Time Gesture Tracking Pipelines
To translate webcam frame inputs into robotic movements (like my Smart Robotic Arm control loop), joint offsets are processed locally on the client host using OpenCV and Google's MediaPipe:
  Webcam Frame (30FPS)
          |
          v
  MediaPipe Landmarker (Joints extraction)
          |
          v
  Vector Mapping (Mouth/Hand angles)
          |
          v
  Jitter Smoothing (Moving average)
          |
          v
  WebSocket Client (Send servo angles)
          |
          v
  PCA9685 PWM Driver (Move joints)
By smoothing coordinates on the host side using a moving average filter, we prevent servo jitters and ensure fluid robotic joints rotation with sub-50ms latency.
My AI Automation Process
I develop AI features through iterative evaluation, ensuring model accuracy is verified against real edge queries.
01. Feasibility Study
Defining Accuracy Boundaries
Phase 1 of 9
We outline what the AI system must do. I analyze if the requirements can be met with structured prompting, a RAG vector backend, or if it requires a specialized local vision or voice model.
Featured Project Deliverables
Dynamic projects fetched from the portfolio database demonstrating execution.
Gesture-controlled multi-axis arm with computer vision.
ESP32OpenCVMediaPipeWebSockets
Firmware & System Engineer
View Details →
Why Hire a Specialized AI Systems Engineer?
Agencies often drag out projects by attempting custom model training. I integrate proven foundation APIs with lightweight local edge ML, cutting delivery times in half.
Integration Factor
My AI Engineering
Typical Agency / Wrapper Boilerplate
Hallucination Protection
✓ Vector similarity checks and strict context boundaries prevent models from lying.
❌ Simple chat templates that easily drift and hallucinate off-topic.
Edge AI / Local Offline Inference
✓ Quantized model integration directly on physical hardware (ESP32-S3).
❌ Lacks hardware understanding; relies entirely on cloud API calls.
Security & Abuse Safeguards
✓ Zod schema checks, rate limiters, and system instruction guardrails.
⚠️ Vulnerable to prompt injection; easily abused to rack up bills.
Interface Interactivity
✓ Context-aware inputs and interactive elements (like sliding forms).
❌ Basic chat windows that only display static Markdown outputs.
Coverage Area & Physical Location
India is 4½ to 5½ hours ahead of the UK, so your whole morning overlaps my afternoon for calls and reviews. Quotes are in USD and paid by Wise or international bank transfer. Code lives in your GitHub from day one, and you get a staging link to try at every step.
On-site Delivery Areas
Guwahati
Jorhat
Dibrugarh
Silchar
Nagaon
Tezpur
Tinsukia
Sivasagar
Golaghat
Barpeta
North Lakhimpur
Bongaigaon
Dhubri
Kokrajhar
Hailakandi
Karimganj
Remote Collaboration
For clients across other major Indian tech hubs (Bengaluru, Hyderabad, Pune, Chennai, Mumbai, Delhi NCR) and global locations (US, Canada, UK, Australia, Germany, Singapore), I provide remote collaboration via GitHub, staging API deployments, and sandbox vector database integrations.
Base: Guwahati, Assam, India
Frequently Asked Questions
Answers to what clients ask me most.
Often yes. I connect to tools that offer an API or webhooks, and I use n8n or custom code for the glue. I check your specific setup on the first call before promising anything.
I ground answers in your own documents, show the source, and set it to say it does not know when nothing matches. Anything risky, like quotes or refunds, can be routed to a person.
Yes. Send me your NDA and I will read it and sign it electronically before we go into any details of the project.
Yes. Copy, interface text and documentation can use UK spelling and conventions, and I check it against your existing style if you share a brand guide.
Yes. I work under your NDA and your name, and I am happy to stay out of sight in front of your client while you hold the relationship.
RAG is a technique where an LLM is paired with a searchable database of embeddings. When a user asks a question, the system searches the database for relevant fragments first, then feeds those fragments to the LLM as context. This guarantees factual answers.
I use current models from Google, OpenAI and Anthropic and pick per task: a fast, low-cost model for quick answers, a stronger one for complex data structuring. We settle on the right fit once I know your use case.
It depends on how many sources the assistant draws on, what it connects to and how much it should do on its own. After a first call I give you an estimate for your project, and you get a working version in a staging sandbox early on to try.
Yes. By optimizing pipelines, utilizing lightweight frameworks like MediaPipe, and compiling OpenCV with hardware acceleration, we achieve 30FPS tracking on Raspberry Pi 4/5 or Jetson Nano.
Let's Automate Your Systems with AI
Ready to integrate custom document search, RAG agents, or real-time computer vision into your app? Let's scope the architecture.